LLM Training Data Annotation Services
Prepare structured language datasets for instruction following, task-specific model adaptation, response evaluation, and human preference workflows.
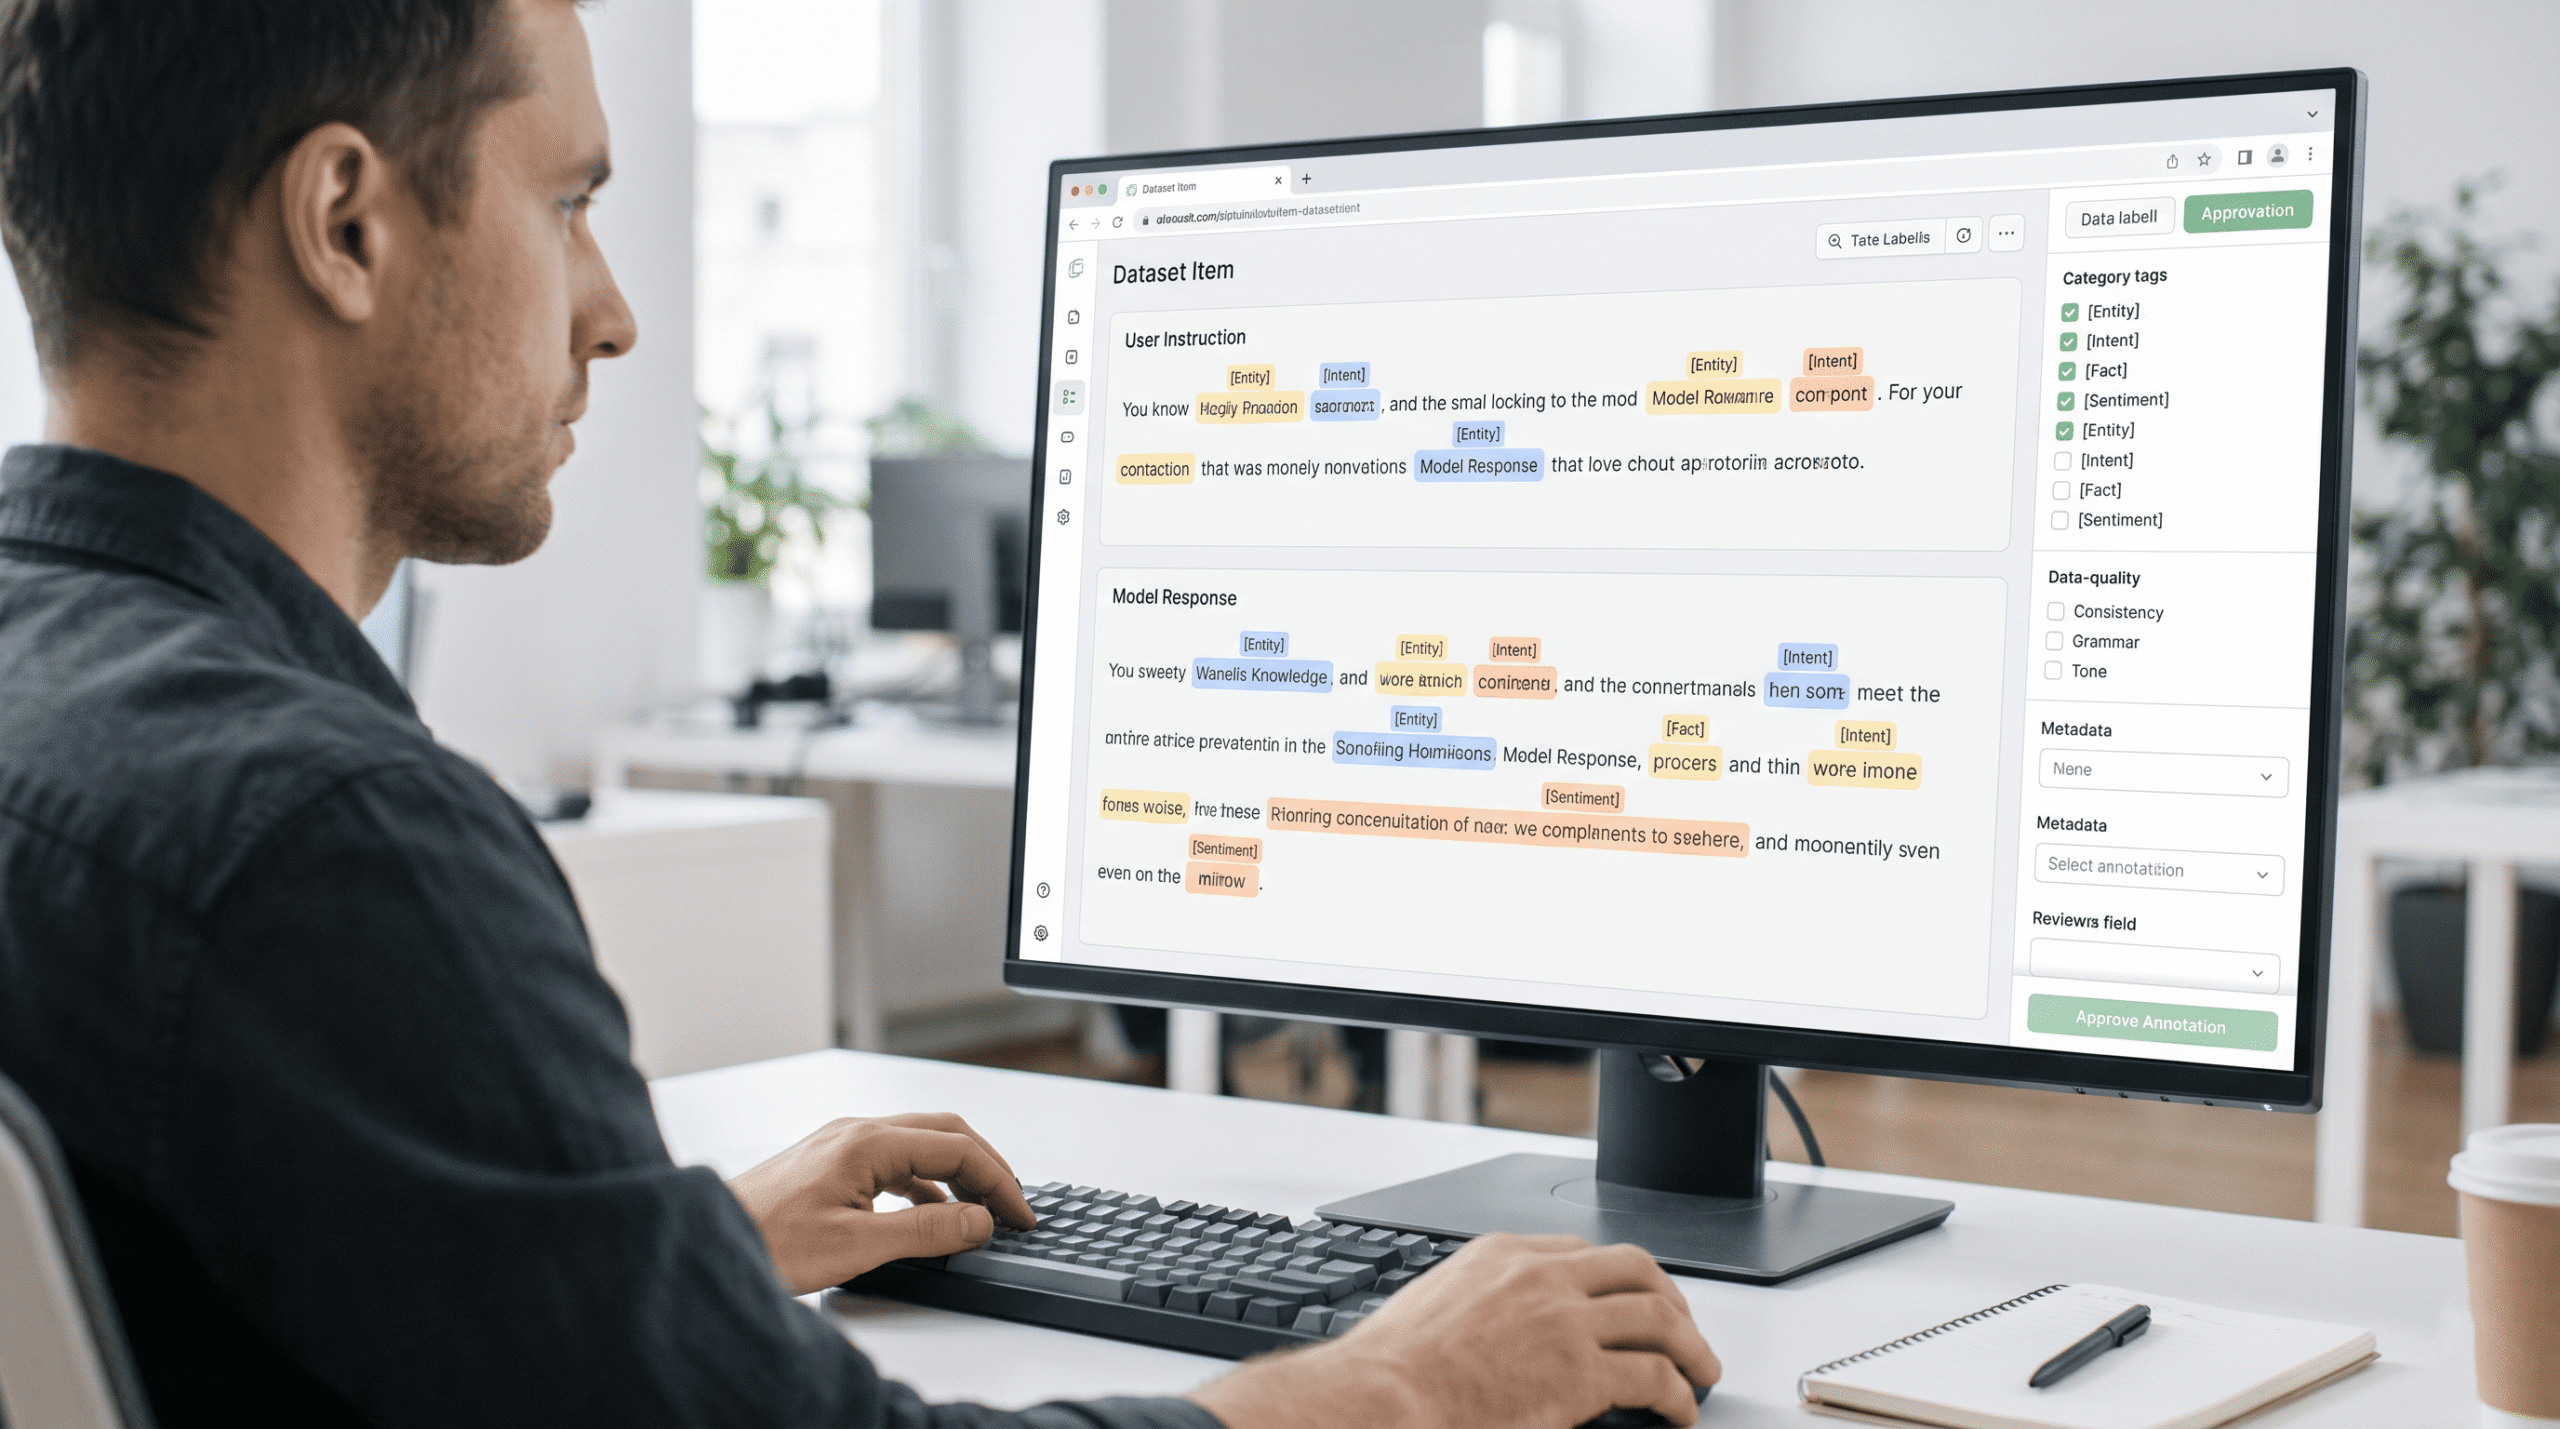
- Instruction-response annotation
- Supervised fine-tuning (SFT) data preparation
- Human preference ranking
- Response evaluation using defined rubrics
- Domain-specific training examples
RLHF Data Annotation Services
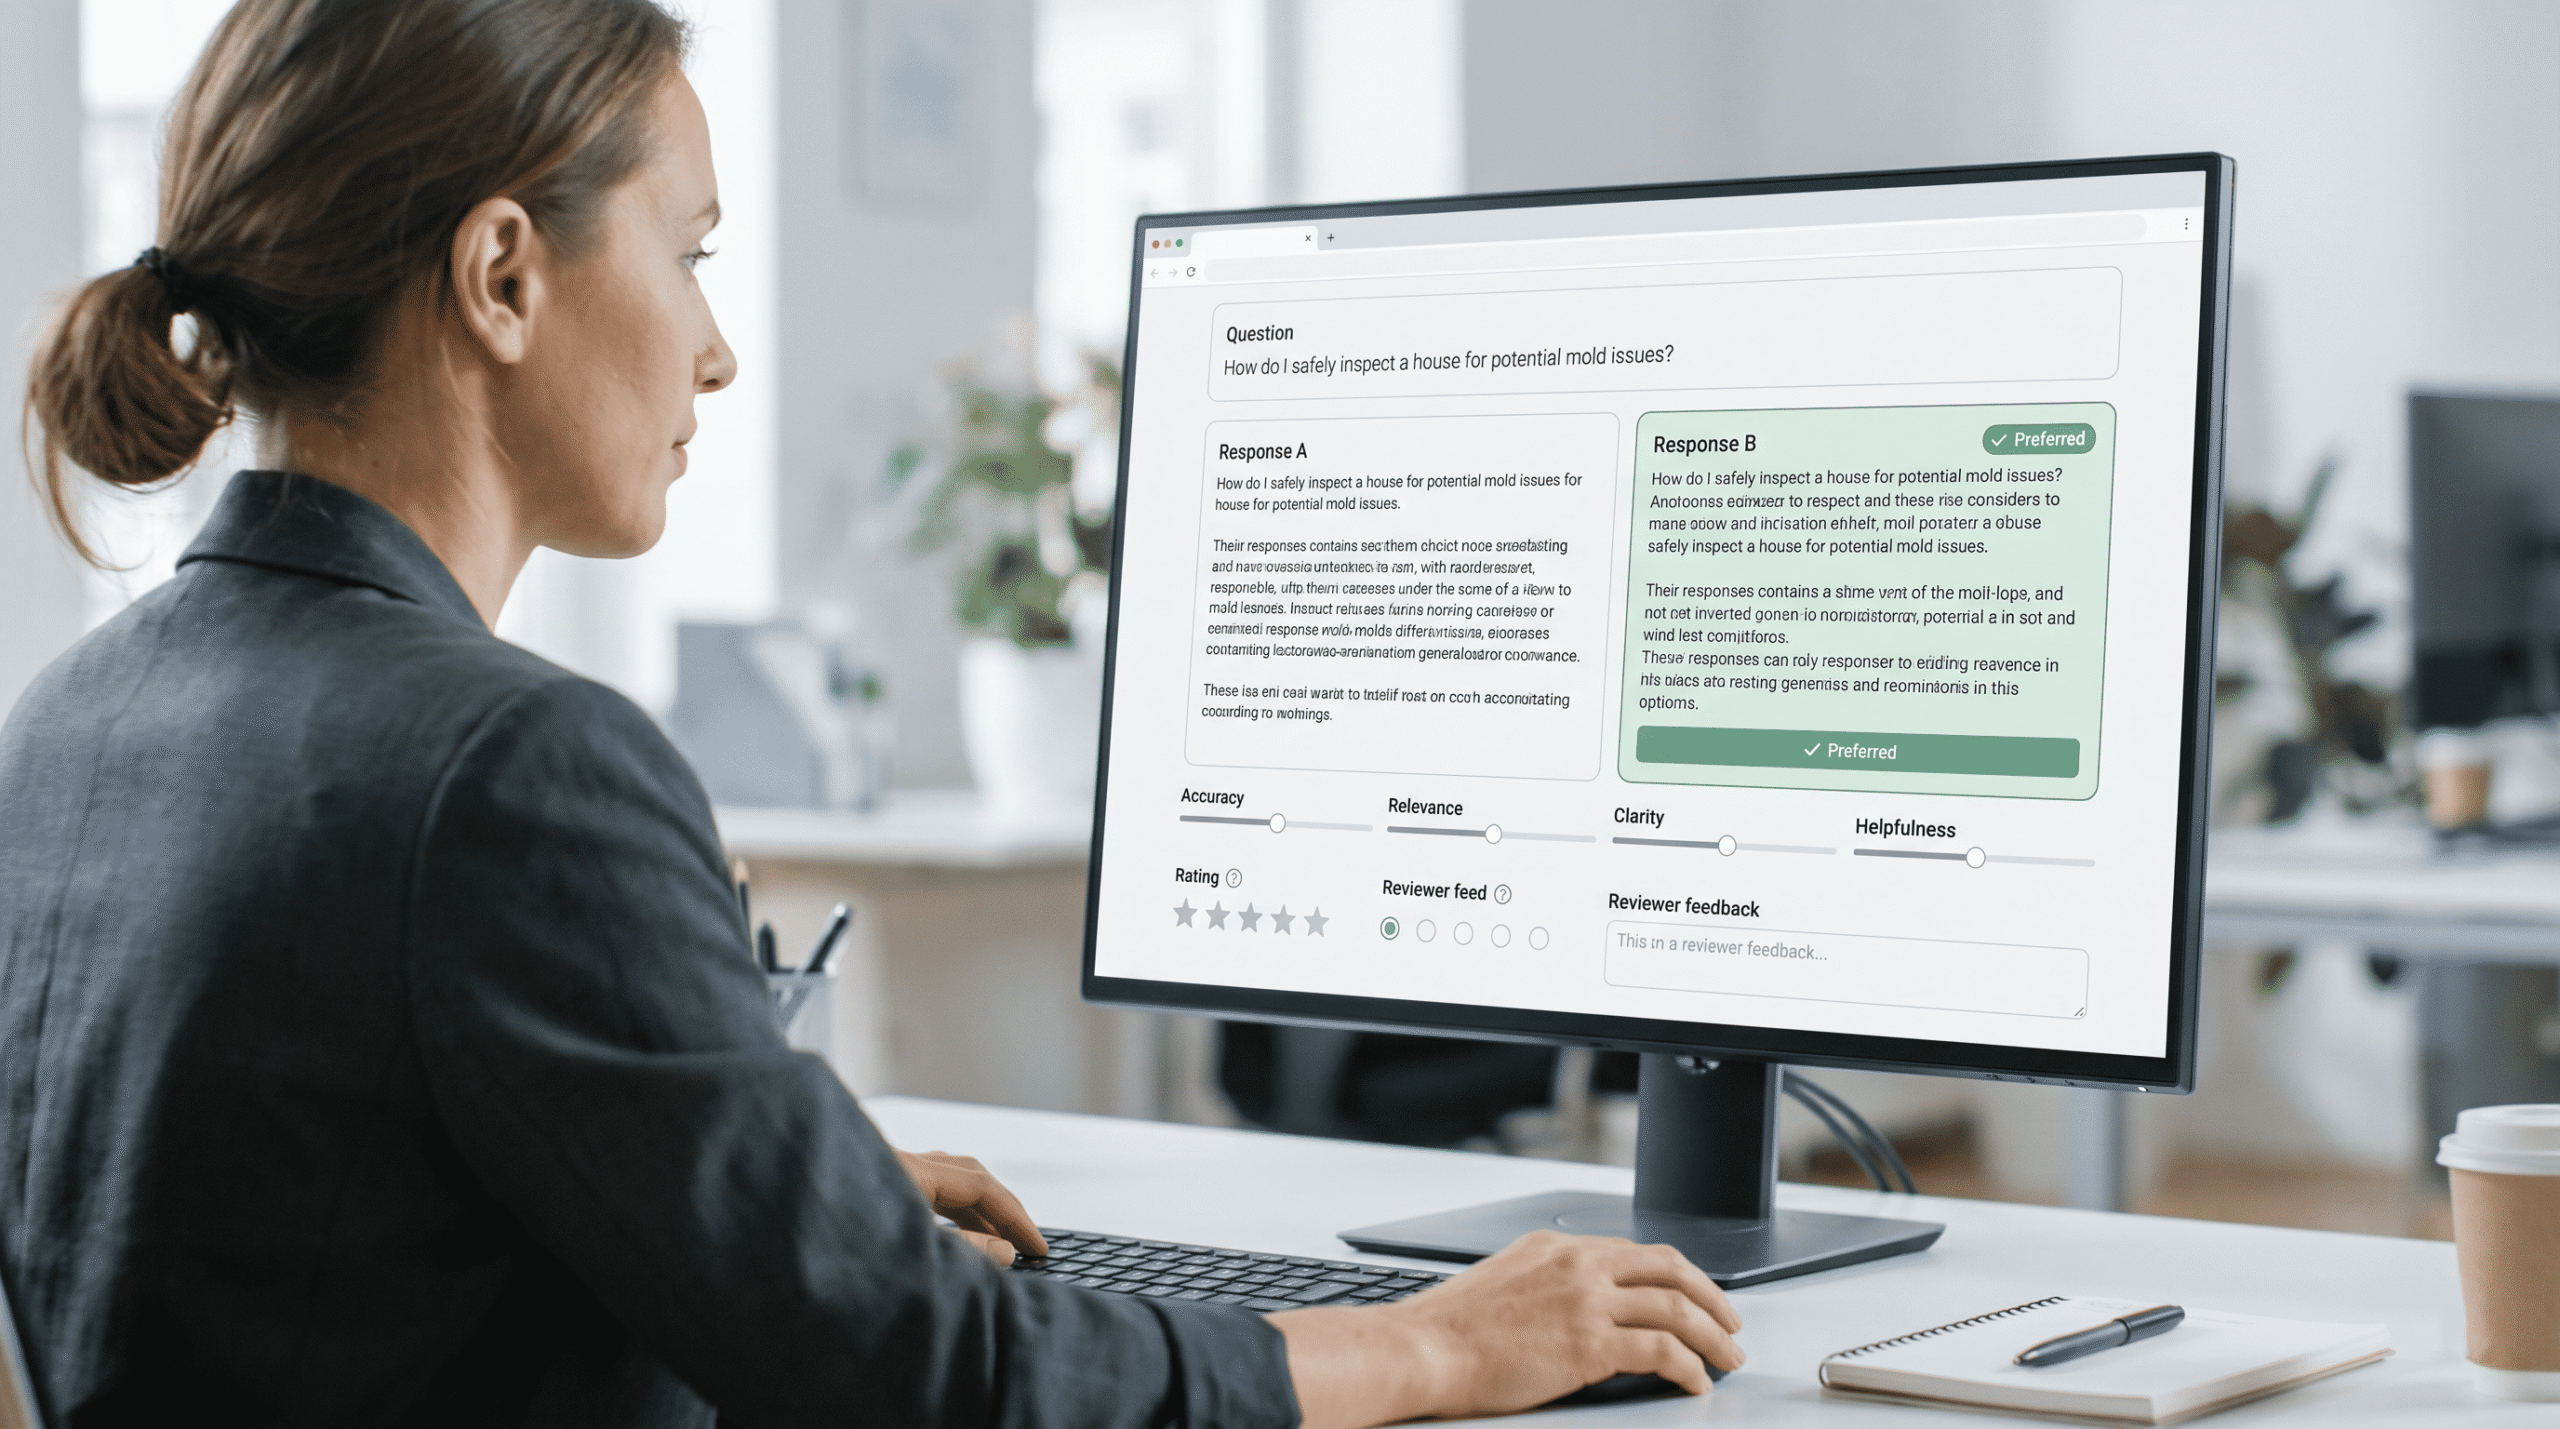
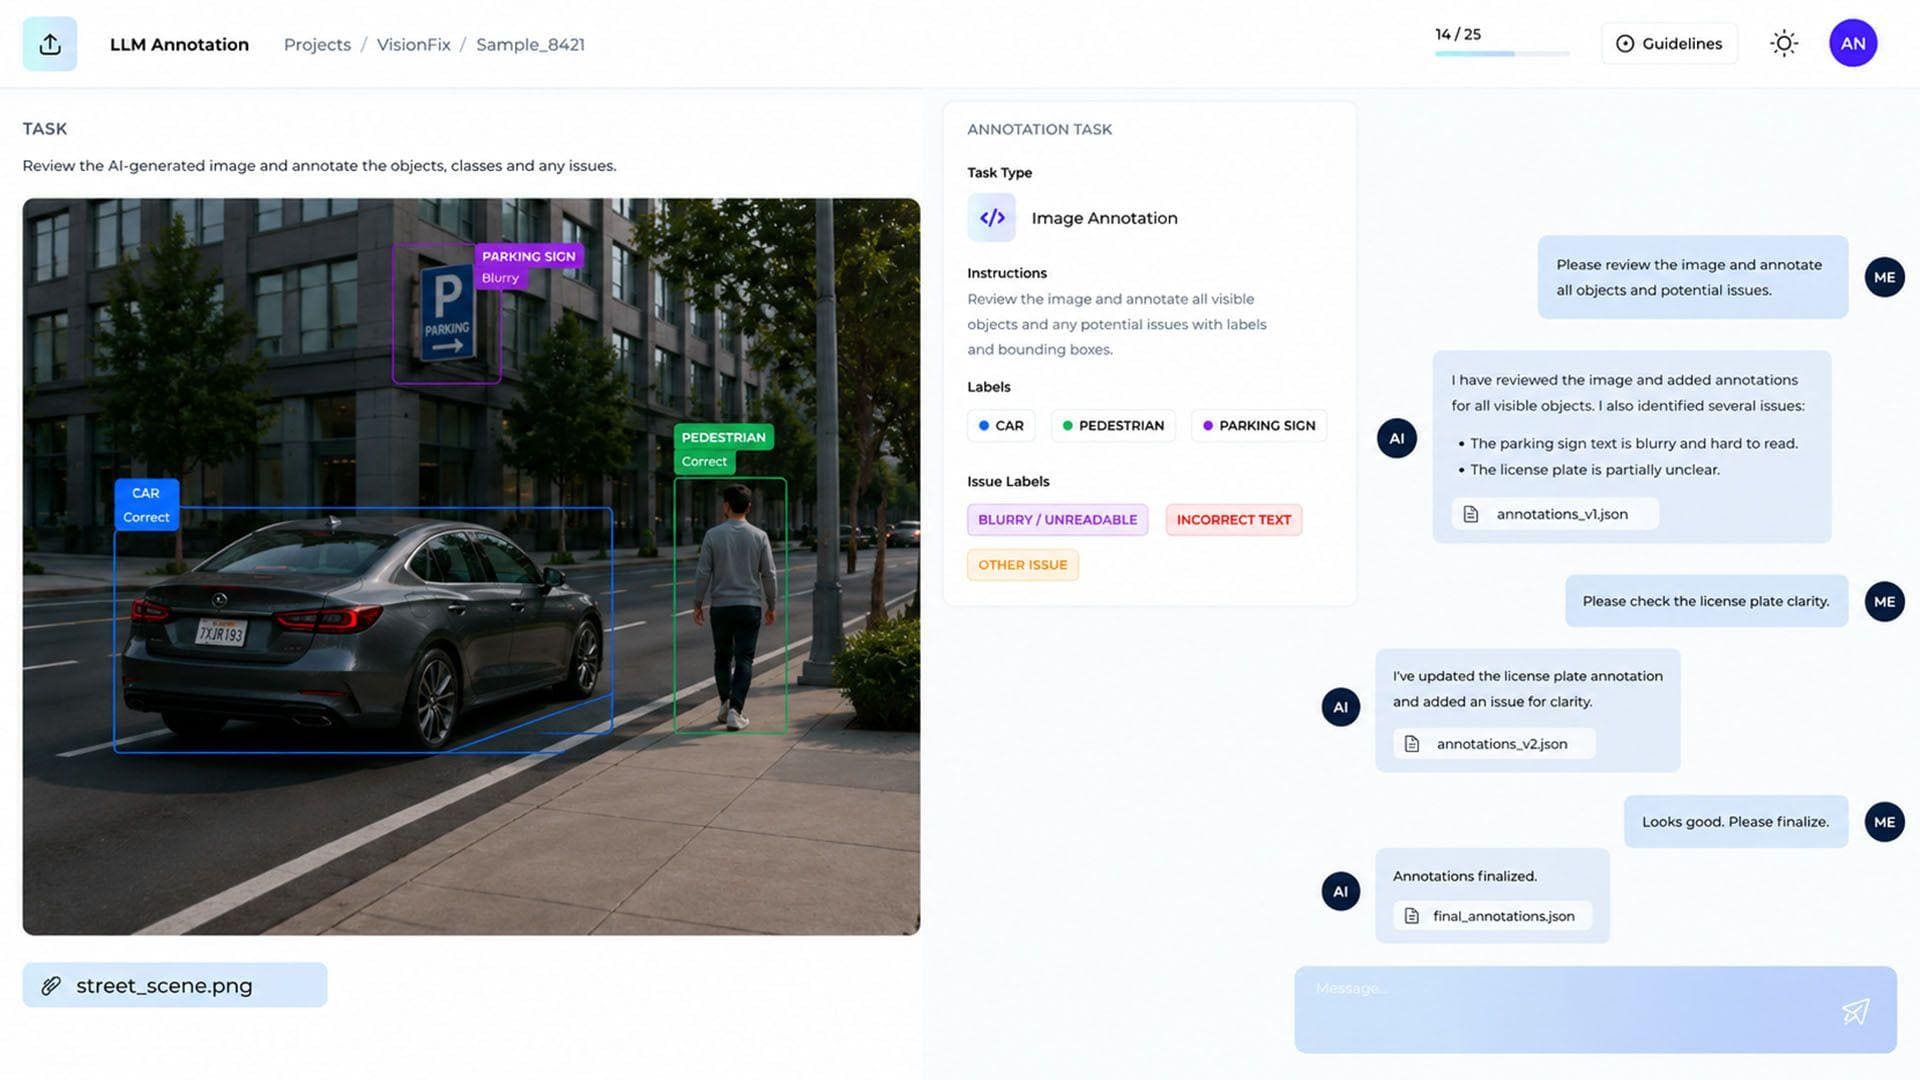
Reinforcement Learning from Human Feedback (RLHF) uses human preferences and other feedback signals as part of a broader model-training process. LabelOps can scope human-feedback annotation workflows around tasks such as response comparison, preference ranking, rubric-based scoring, and response evaluation, where supported. Clear instructions, representative examples, and reviewer calibration help make judgments more consistent across a dataset.
- Ranked response pairs
- Preference labels
- Rubric-based evaluation records
- Annotated feedback datasets
- Quality review outputs
Supervised Fine-Tuning & Instruction Data
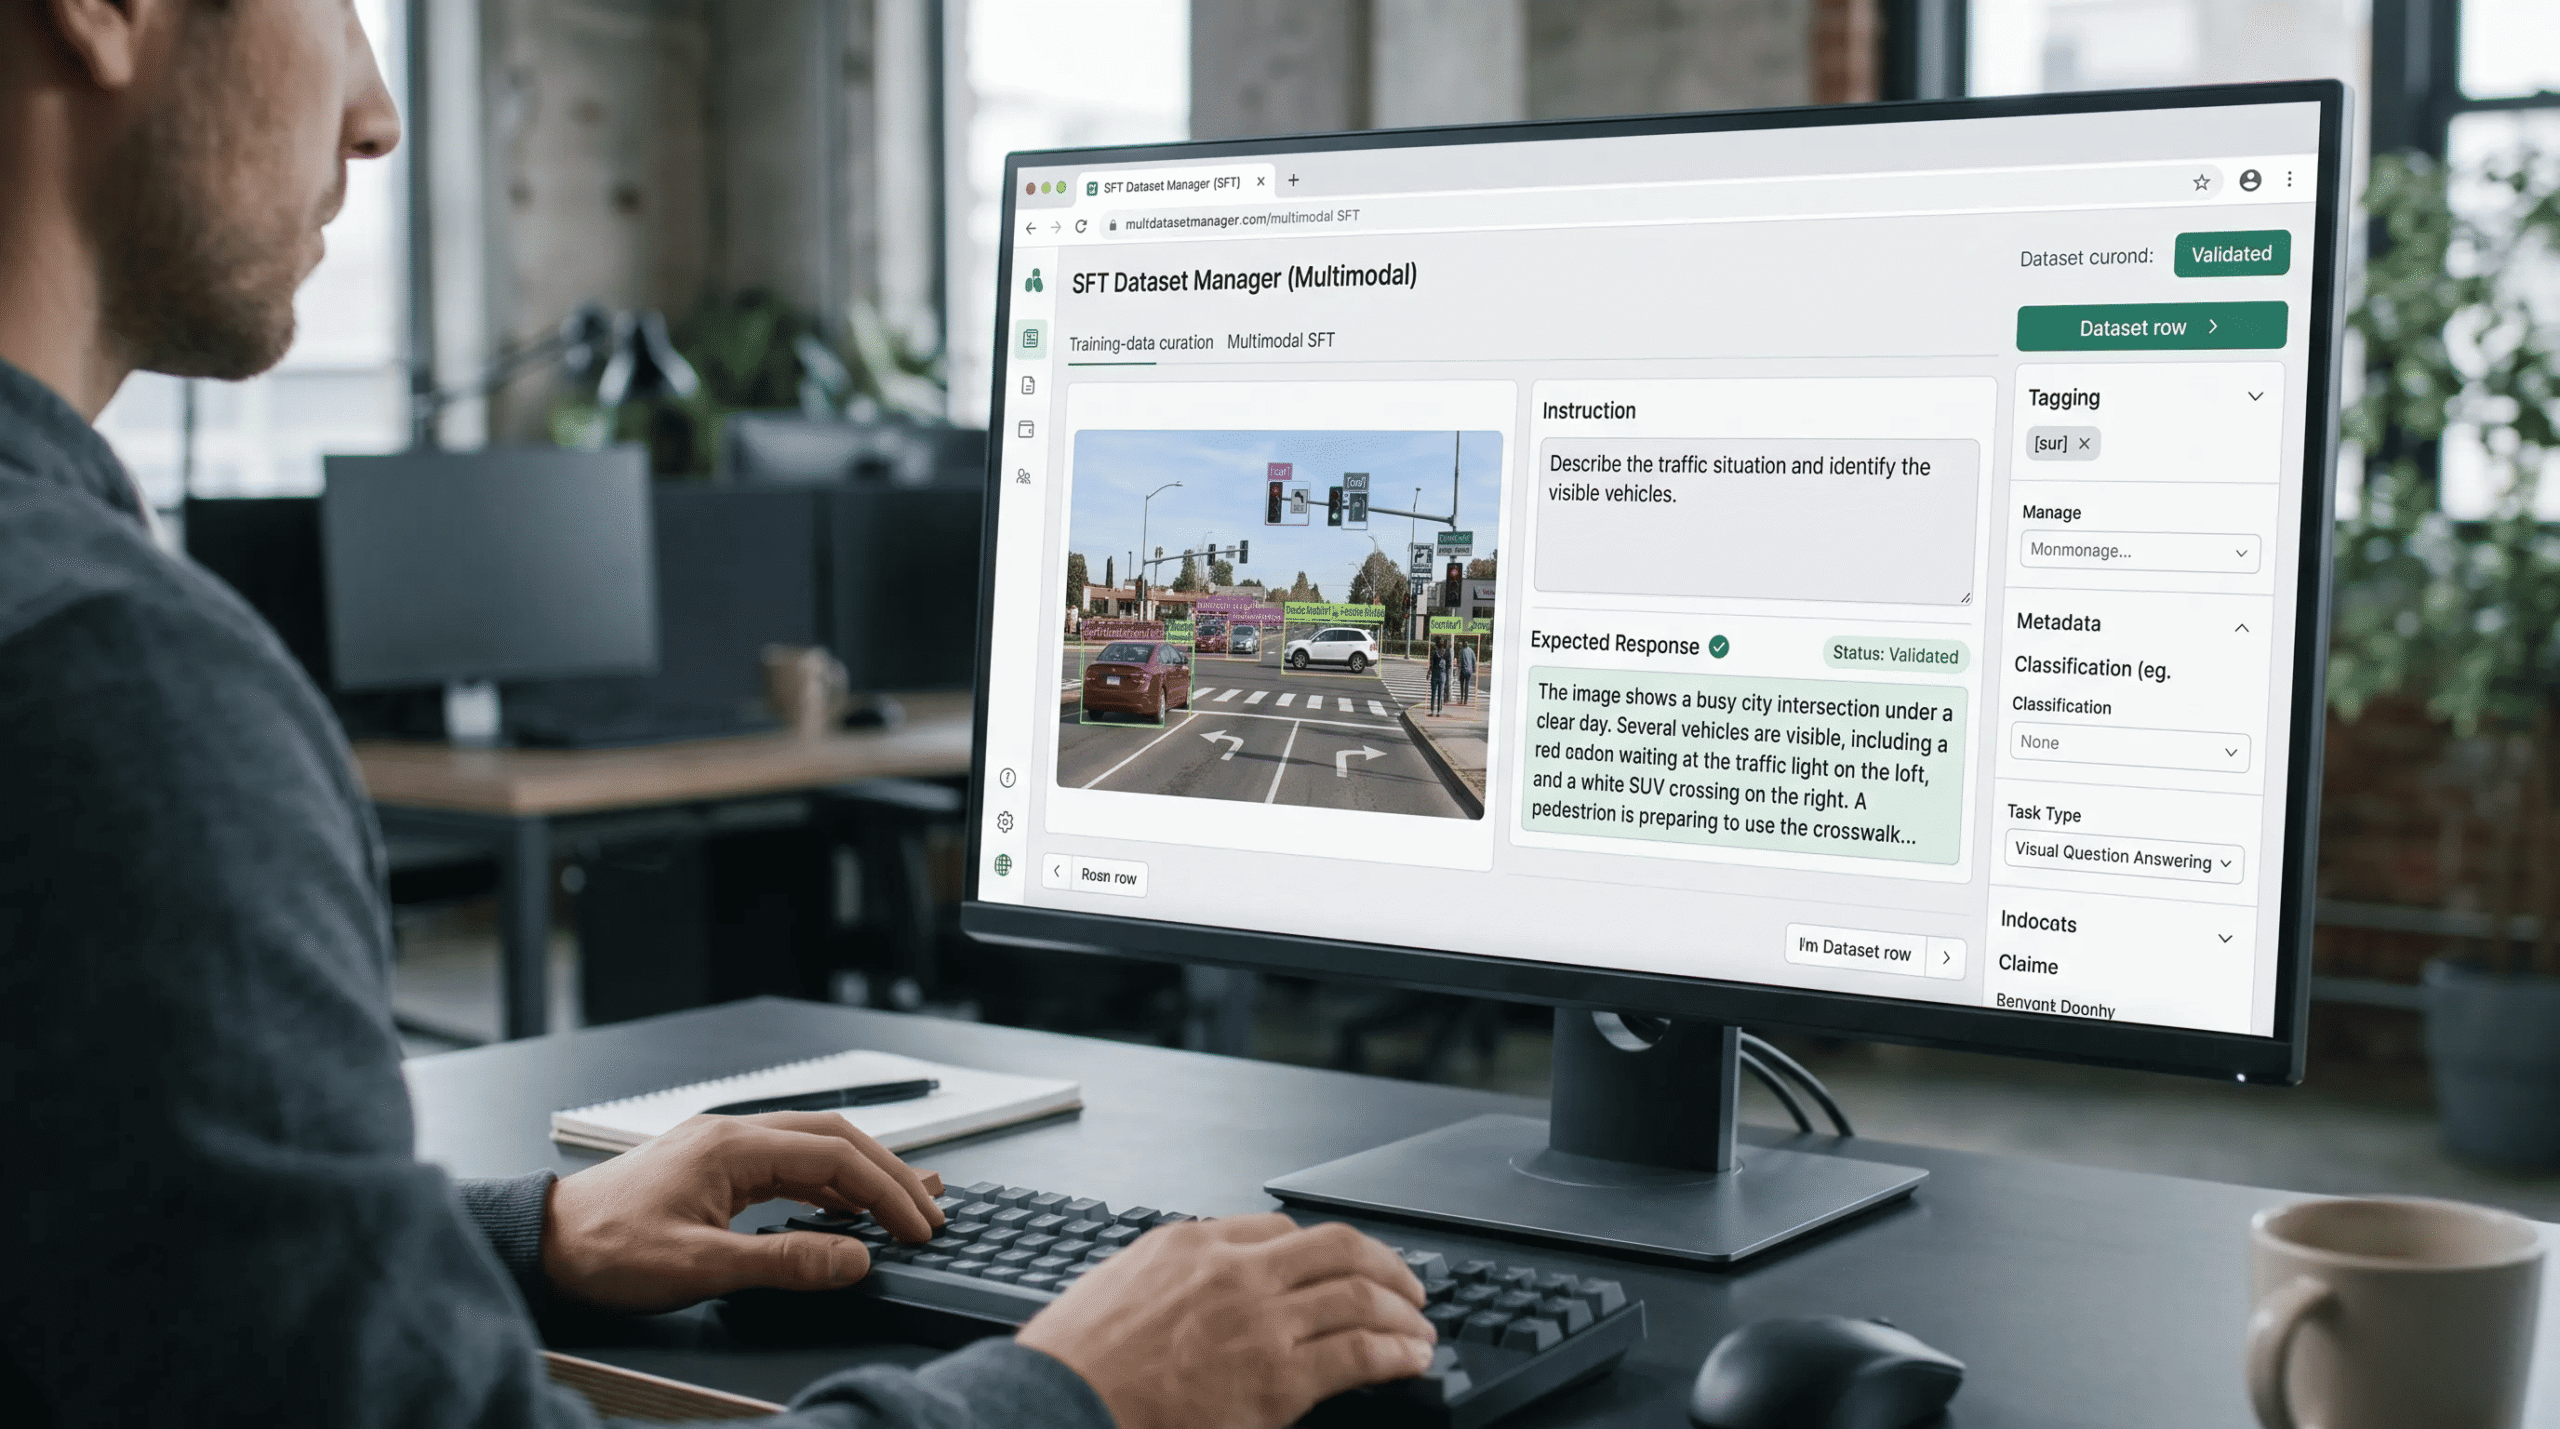
Supervised Fine-Tuning (SFT) uses curated examples to help adapt a model to defined tasks, response formats, and instruction patterns. LabelOps can help prepare instruction-response datasets aligned with a client’s intended use case, subject to the agreed scope and supported services.
- Industry-specific terminology
- Internal knowledge and task instructions supplied by the client
- Preferred response structures and output formats
- Product-specific or workflow-specific tasks
- Domain-specific language and examples
DPO Data Annotation Services
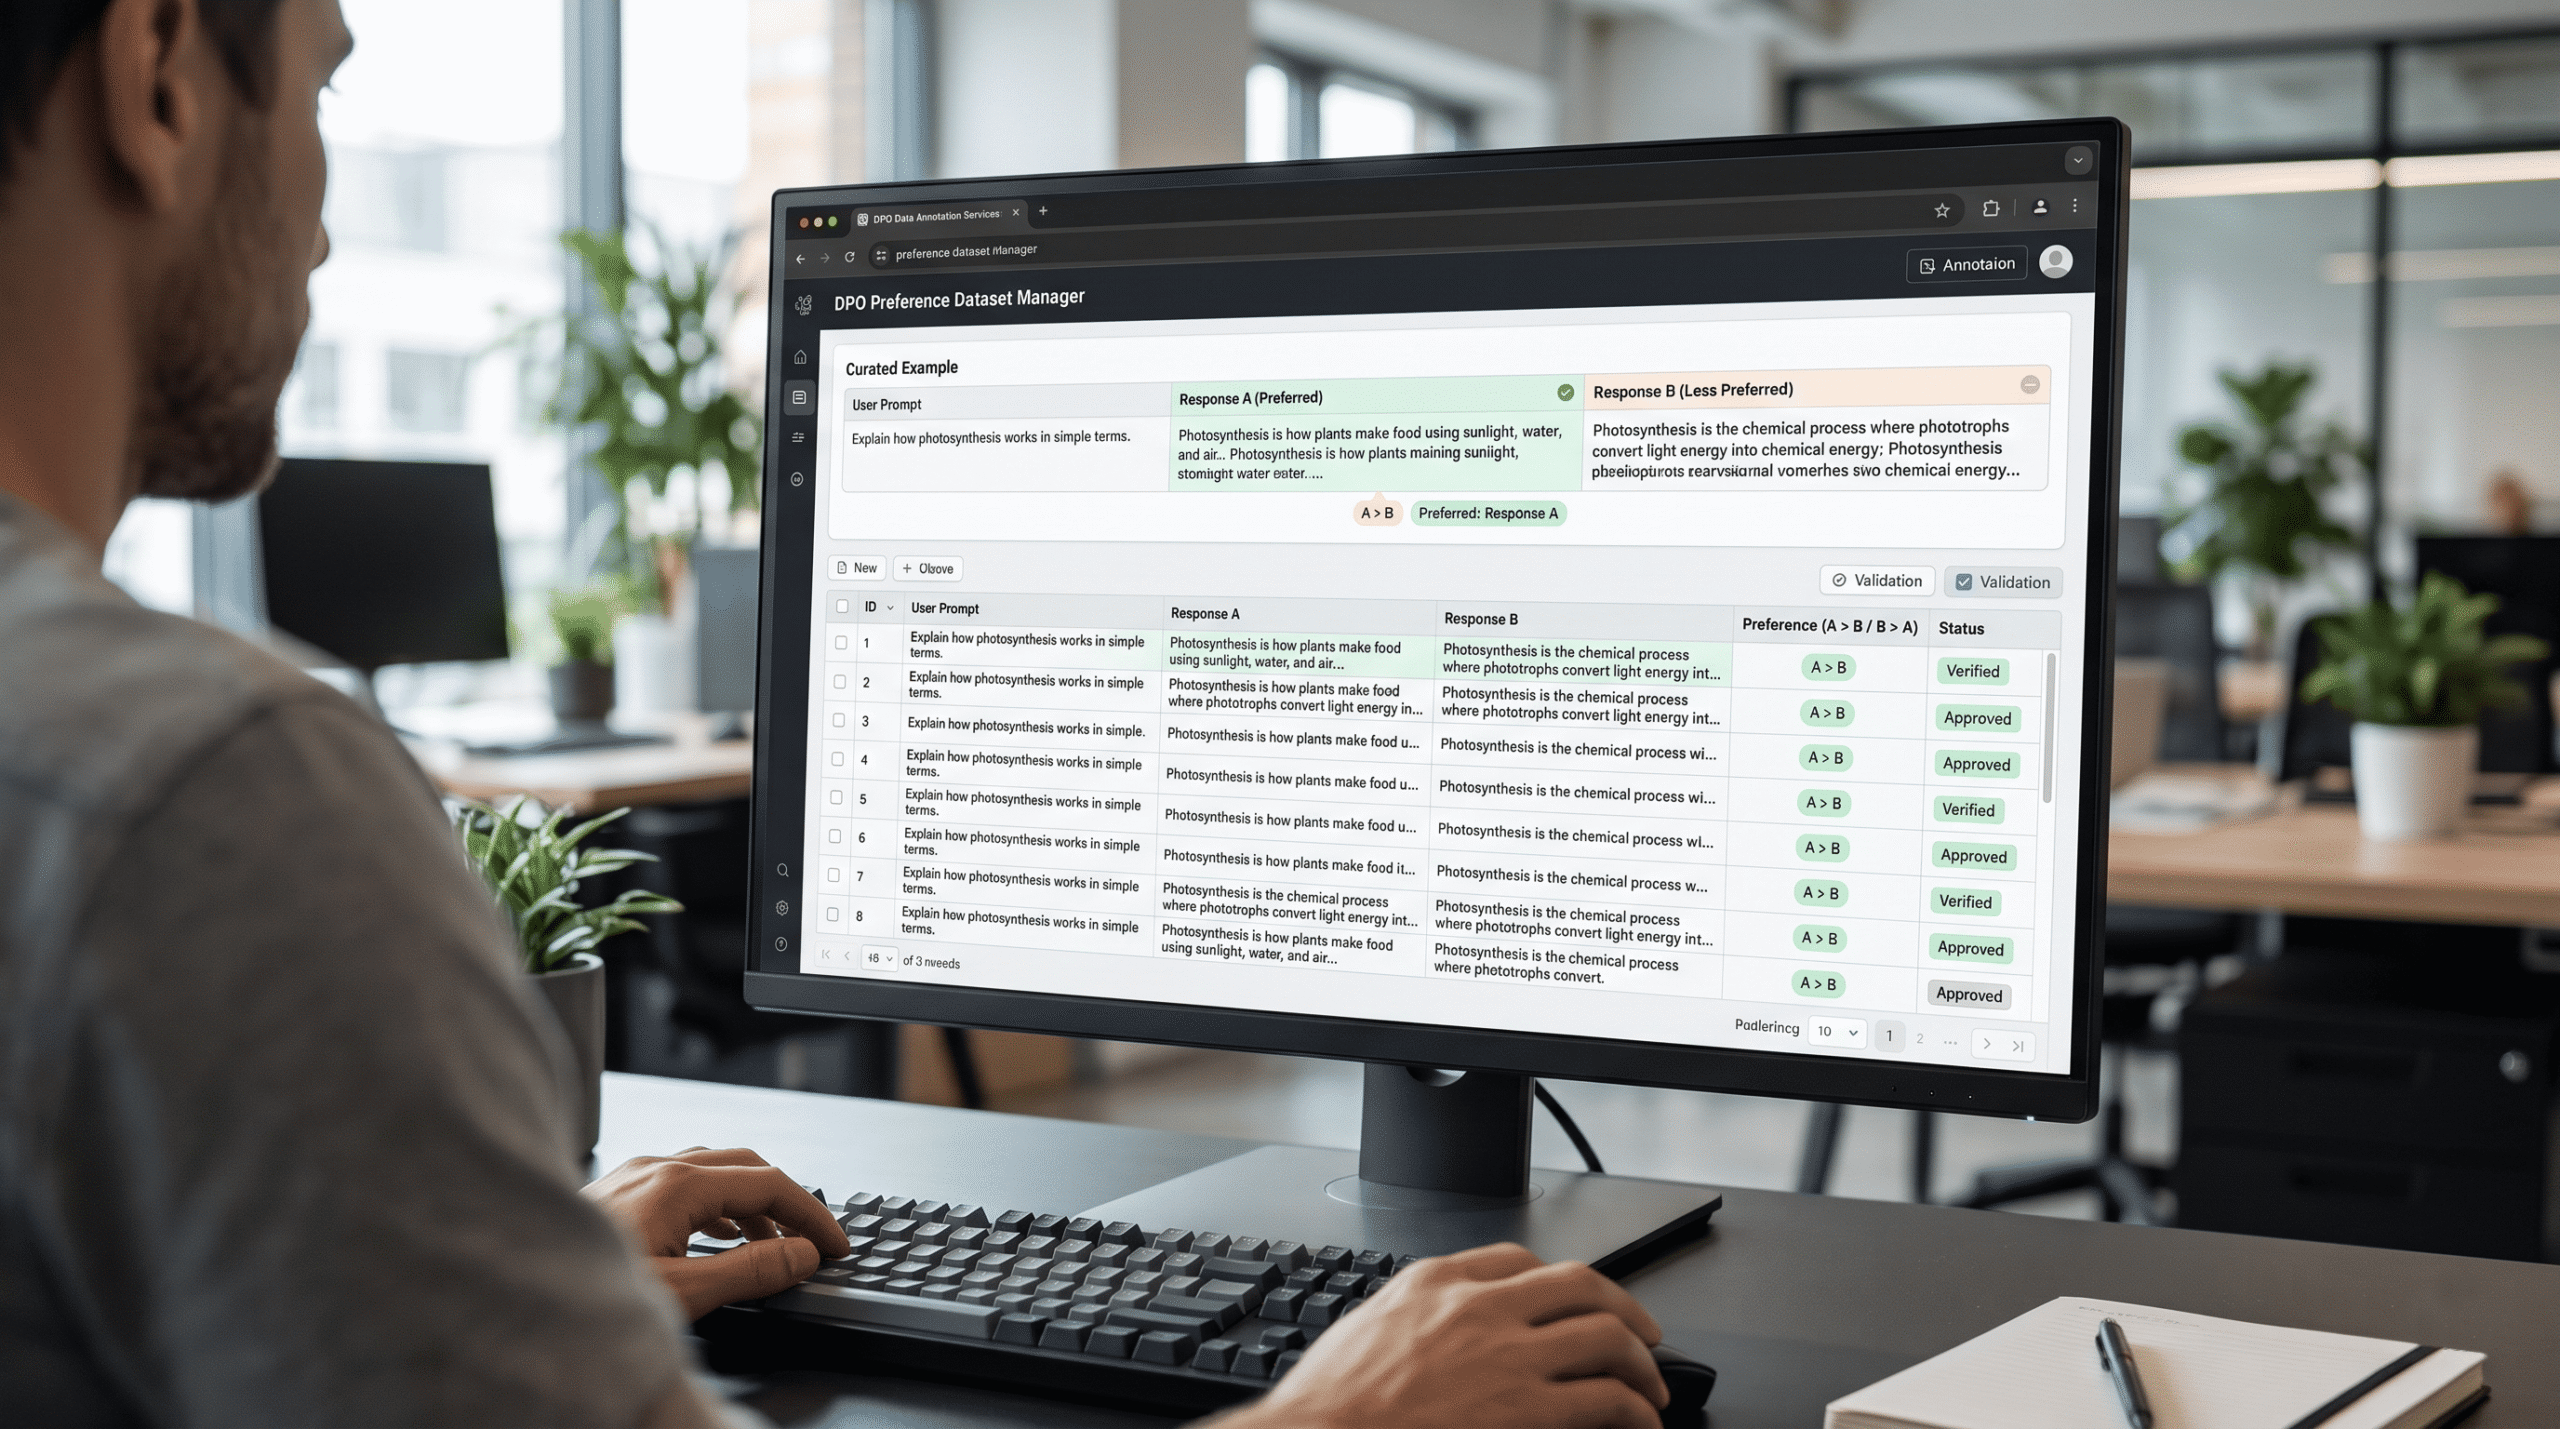
Direct Preference Optimization (DPO) uses preference comparisons to help optimize model behavior. A typical preference dataset contains a prompt, a preferred response, and a less-preferred response. Where this service is supported, LabelOps can scope preference-pair creation or ranking workflows based on client-defined criteria.
Synthetic Data Validation For LLMs
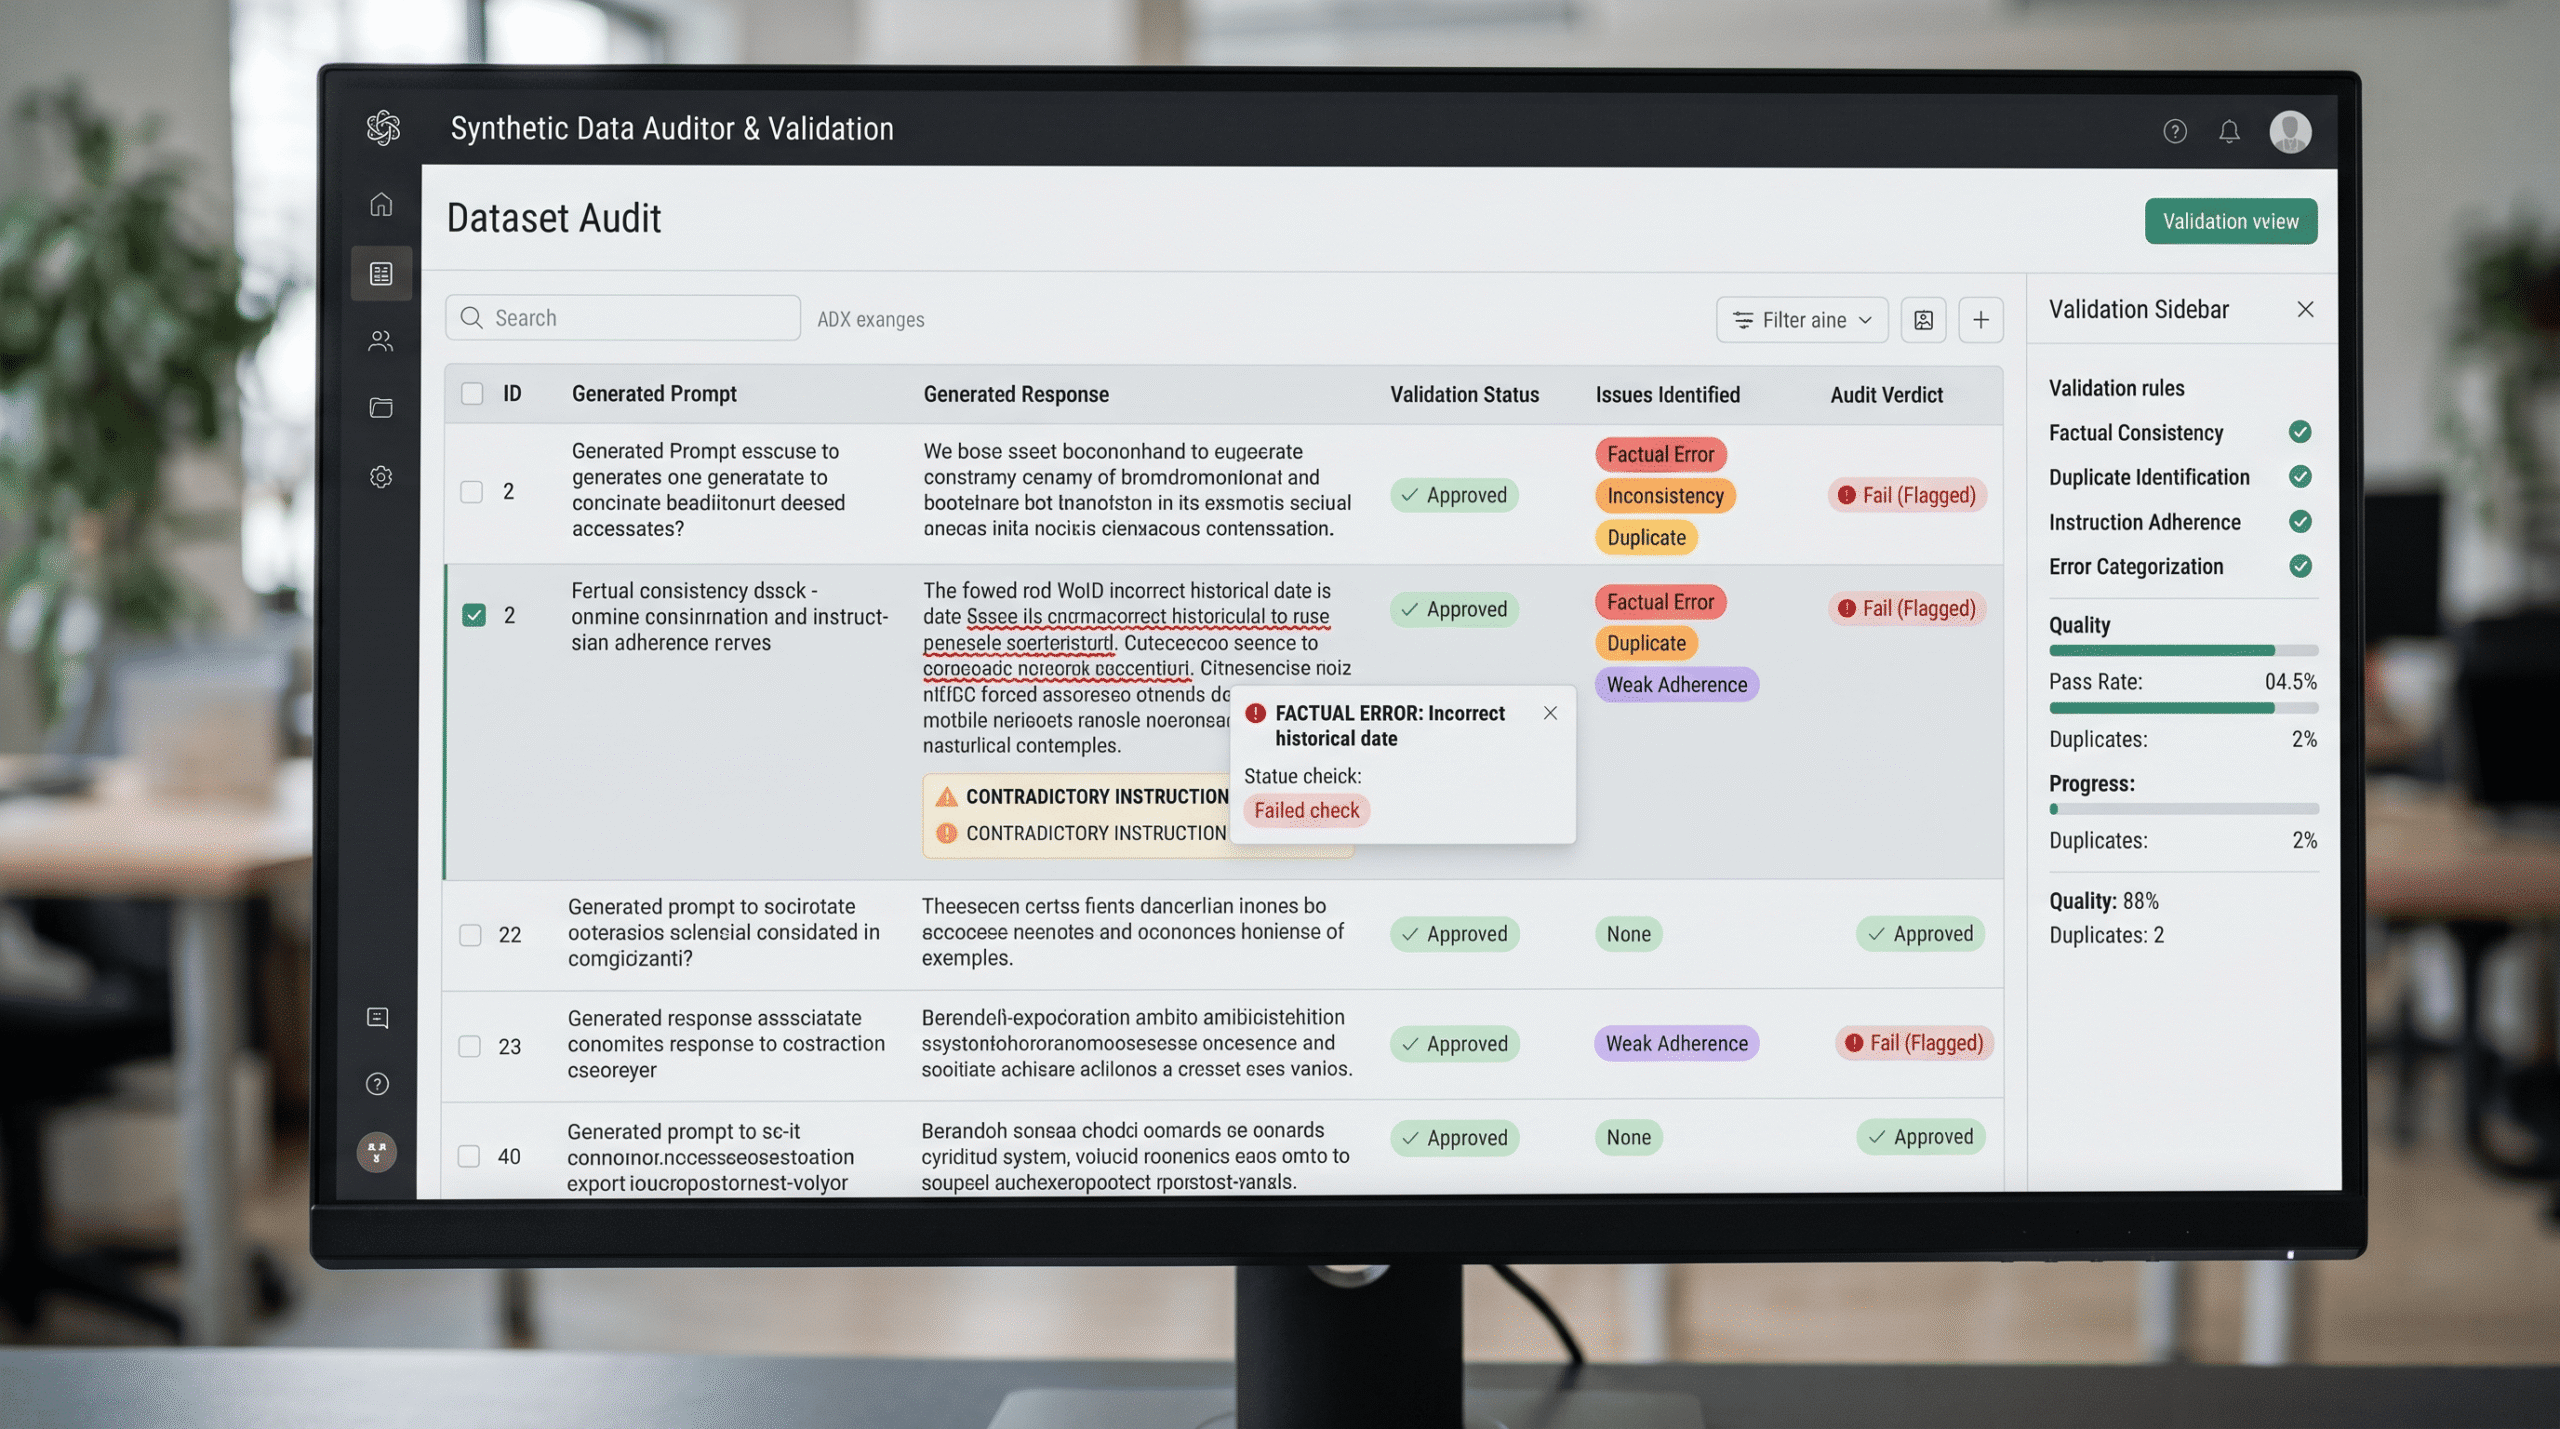
Generated examples may contain factual errors, contradictory instructions, duplication, weak task adherence, or responses that do not meet the intended criteria.
A structured validation workflow can help assess generated datasets against agreed requirements before they are used downstream. Potential activities, subject to service confirmation:
- Rubric-based review
- Factual consistency checks
- Duplicate and inconsistency identification
- Instruction-adherence review
- Error categorization and reporting
VLM Multimodal Data Preparation
Structure relationships between visual inputs and language for vision-language model training and evaluation workflows.
- Image captioning and image-text annotation
- Visual question answering
- Visual grounding
- Video annotation and temporal labeling
- Multimodal response evaluation
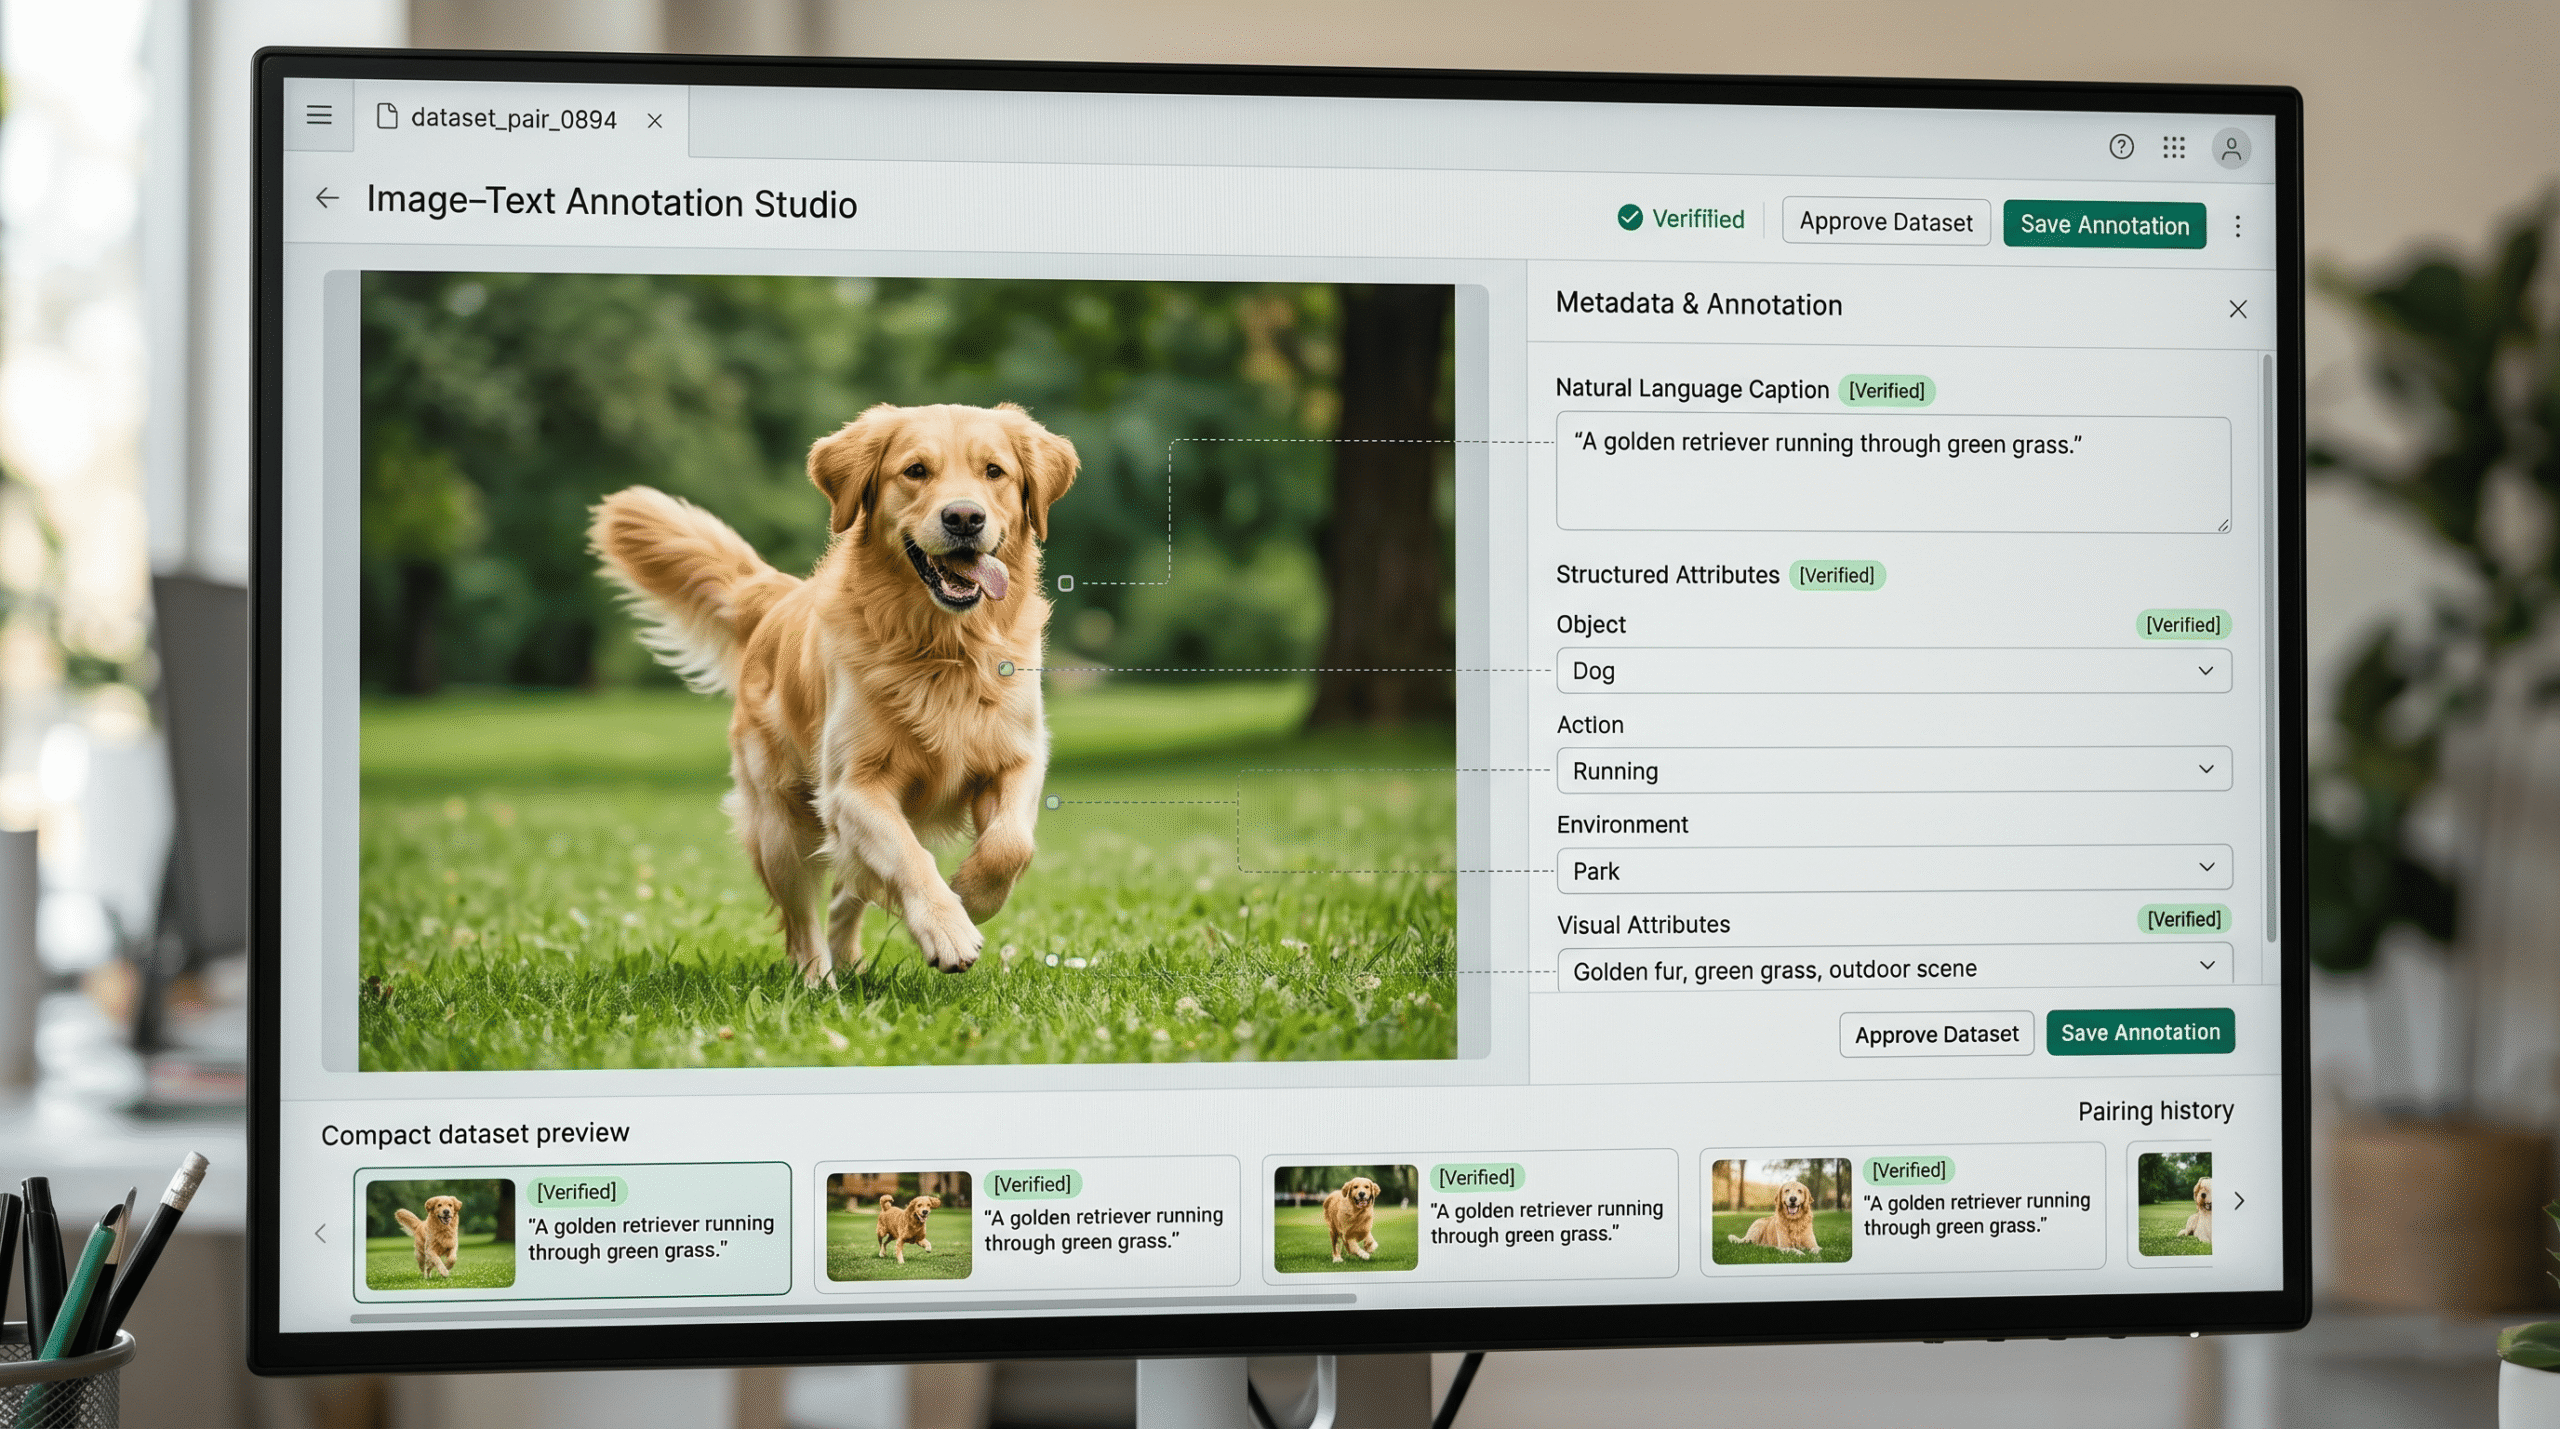
Image-Text Annotation
We help annotate image descriptions, image-text relationships, and visual attributes to prepare structured data for image understanding and multimodal AI applications.
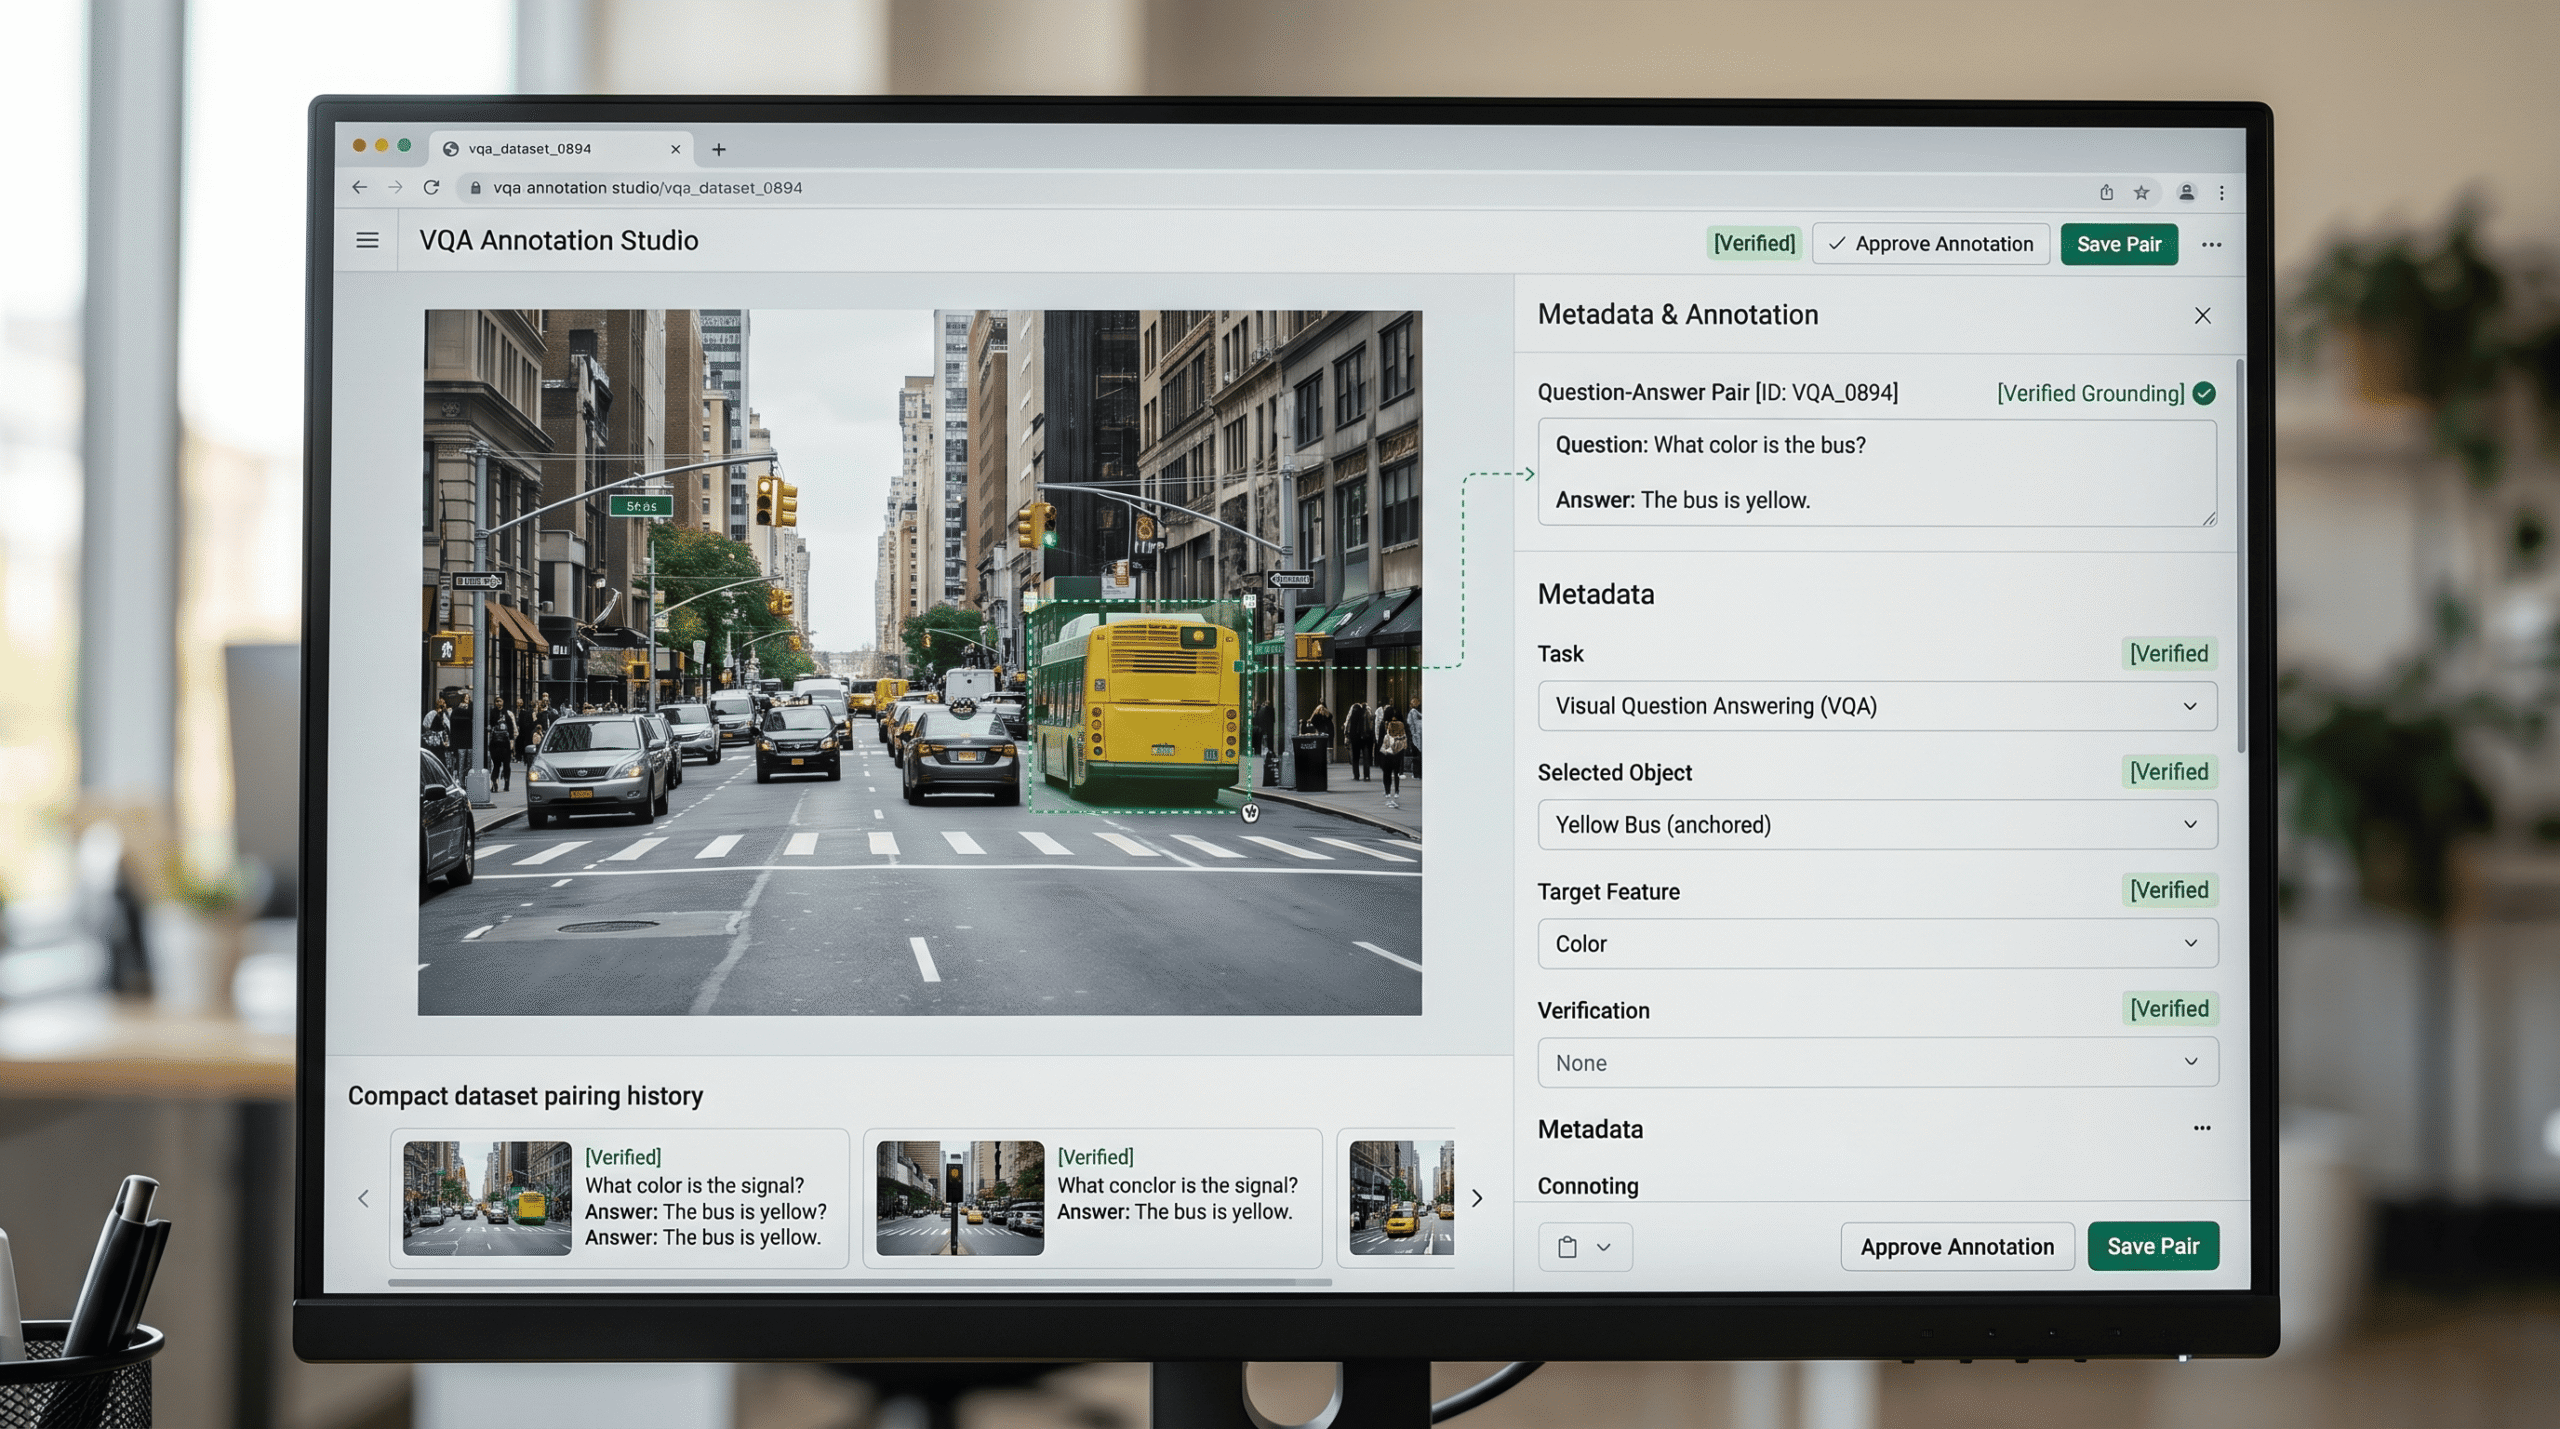
Visual Question Answering
We help create question-and-answer annotations grounded in image content, following defined guidelines for relevance, accuracy, and consistency.
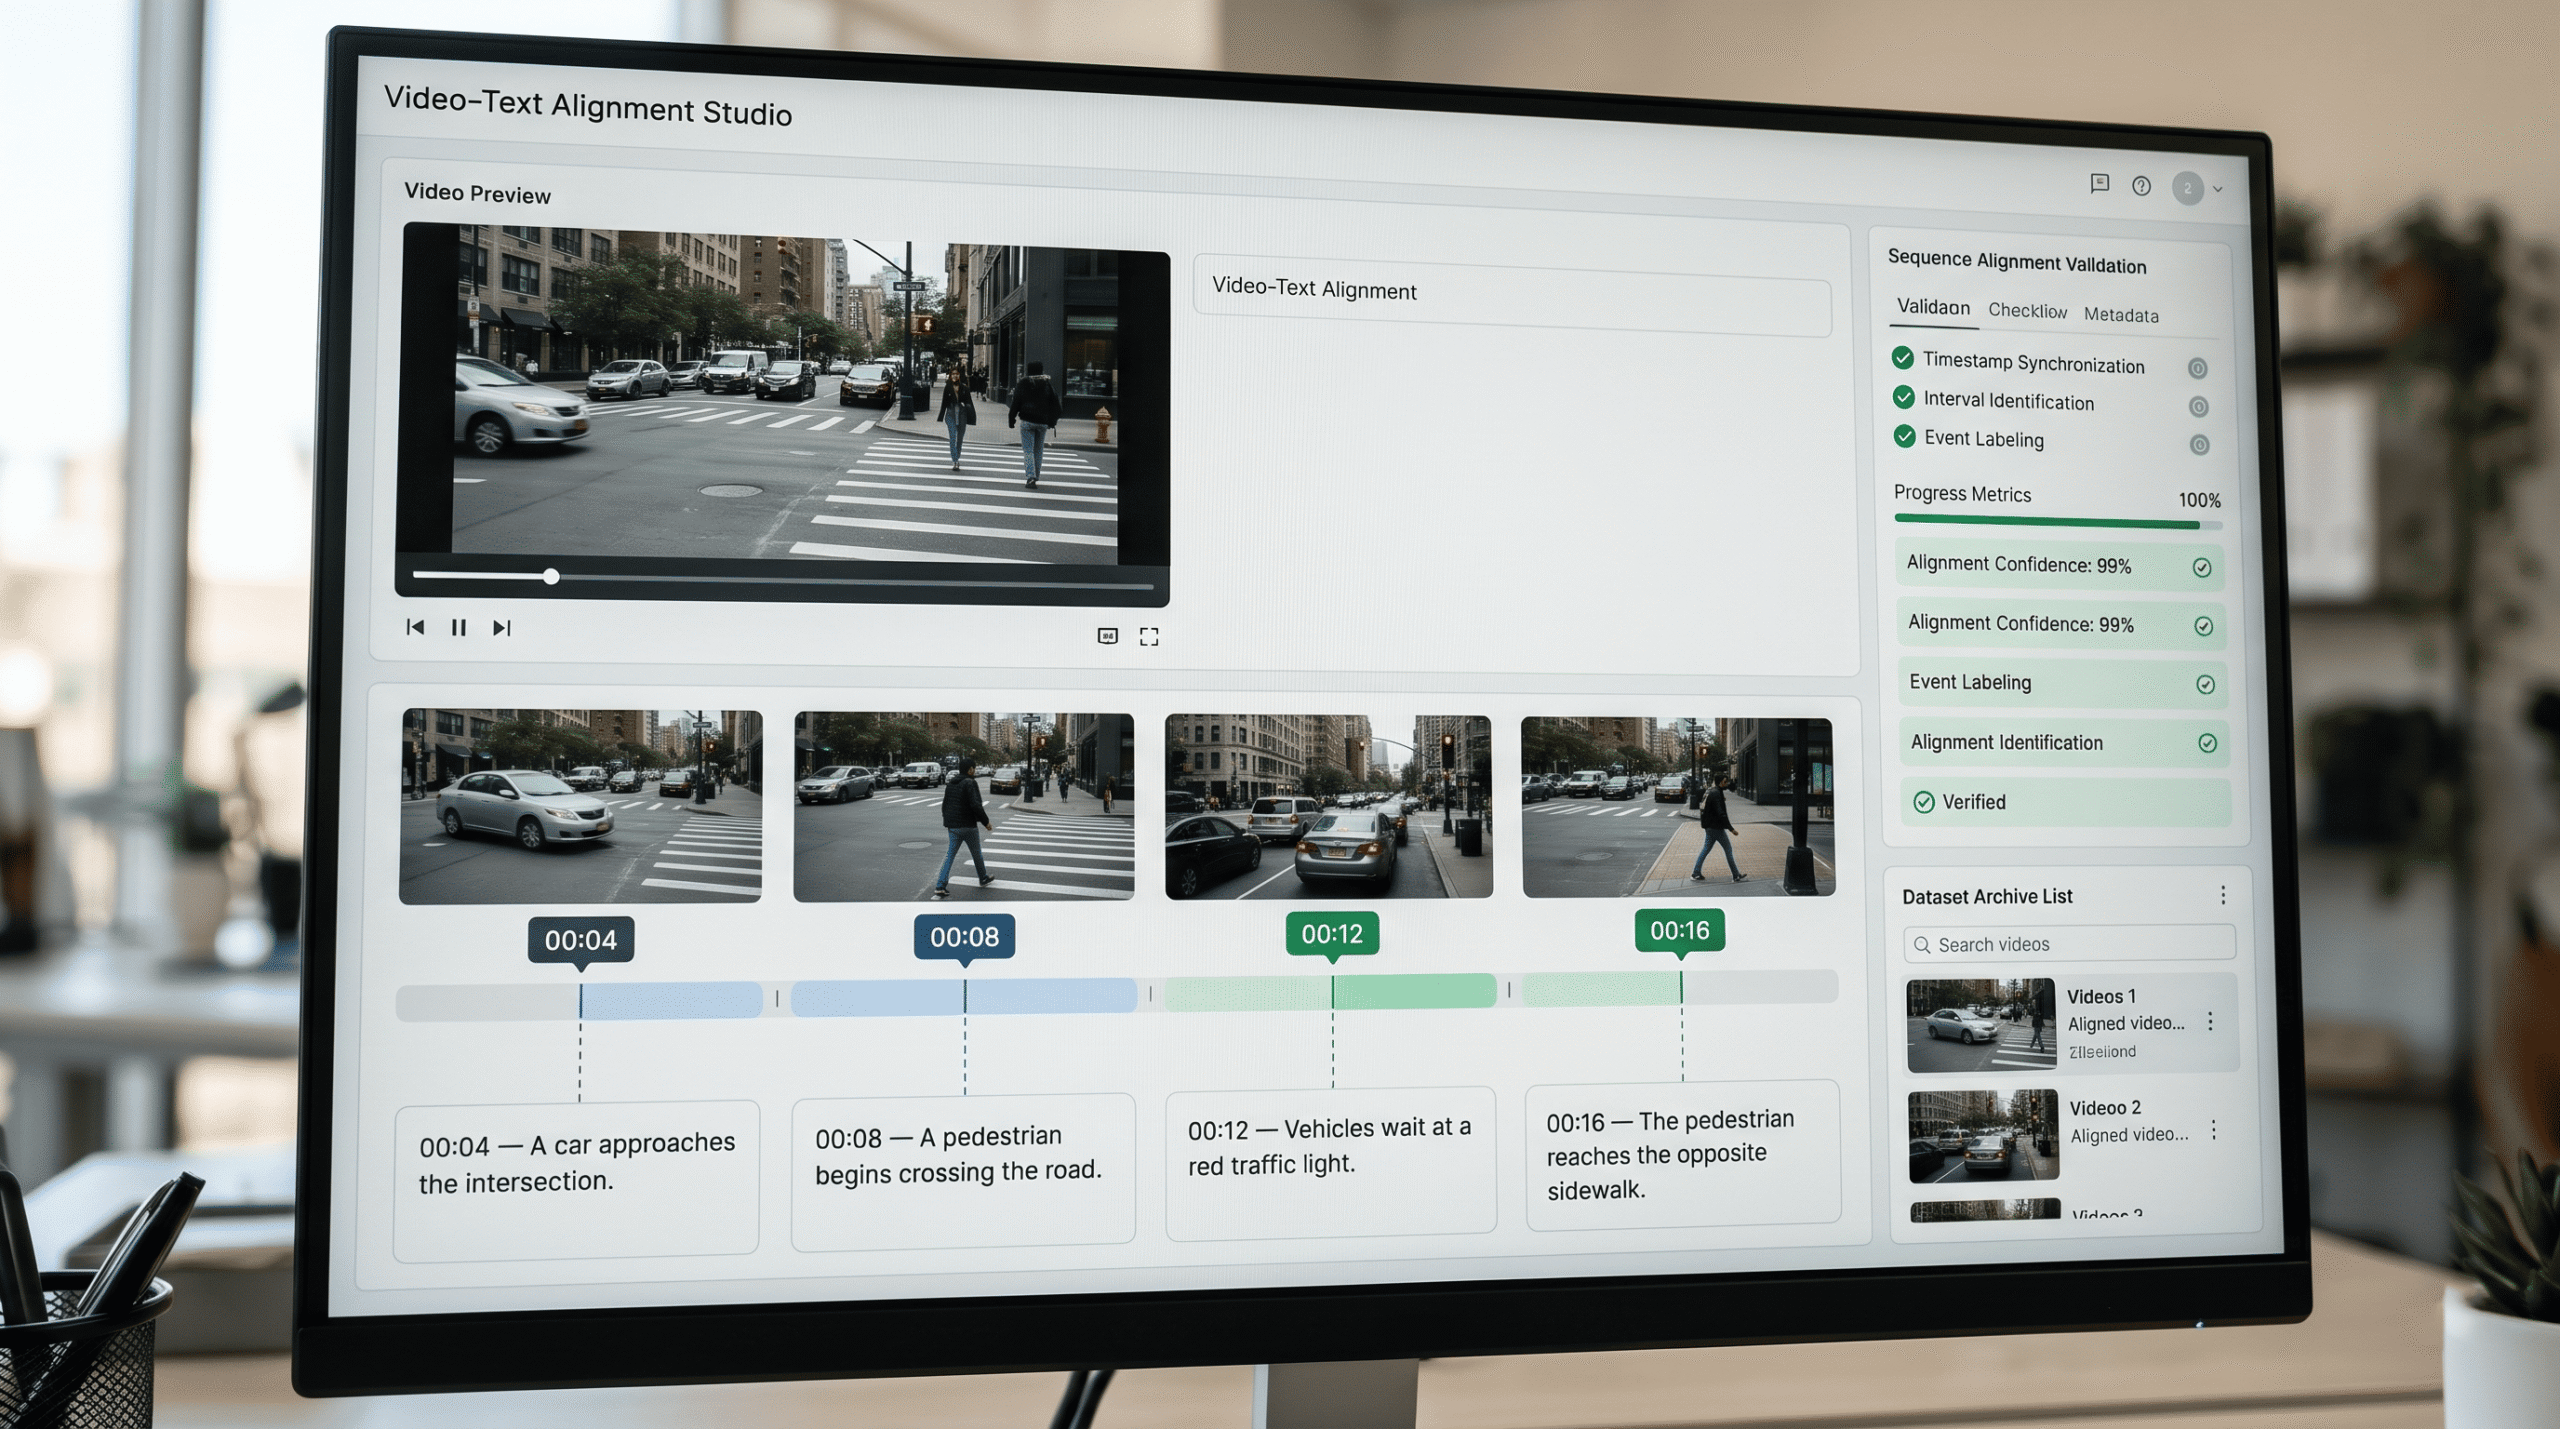
Video-Text Alignment
For supported projects, video-text annotation can connect descriptions with relevant frames, timestamps, or events across a video sequence.
Secure RLHF Annotation for Frontier AI
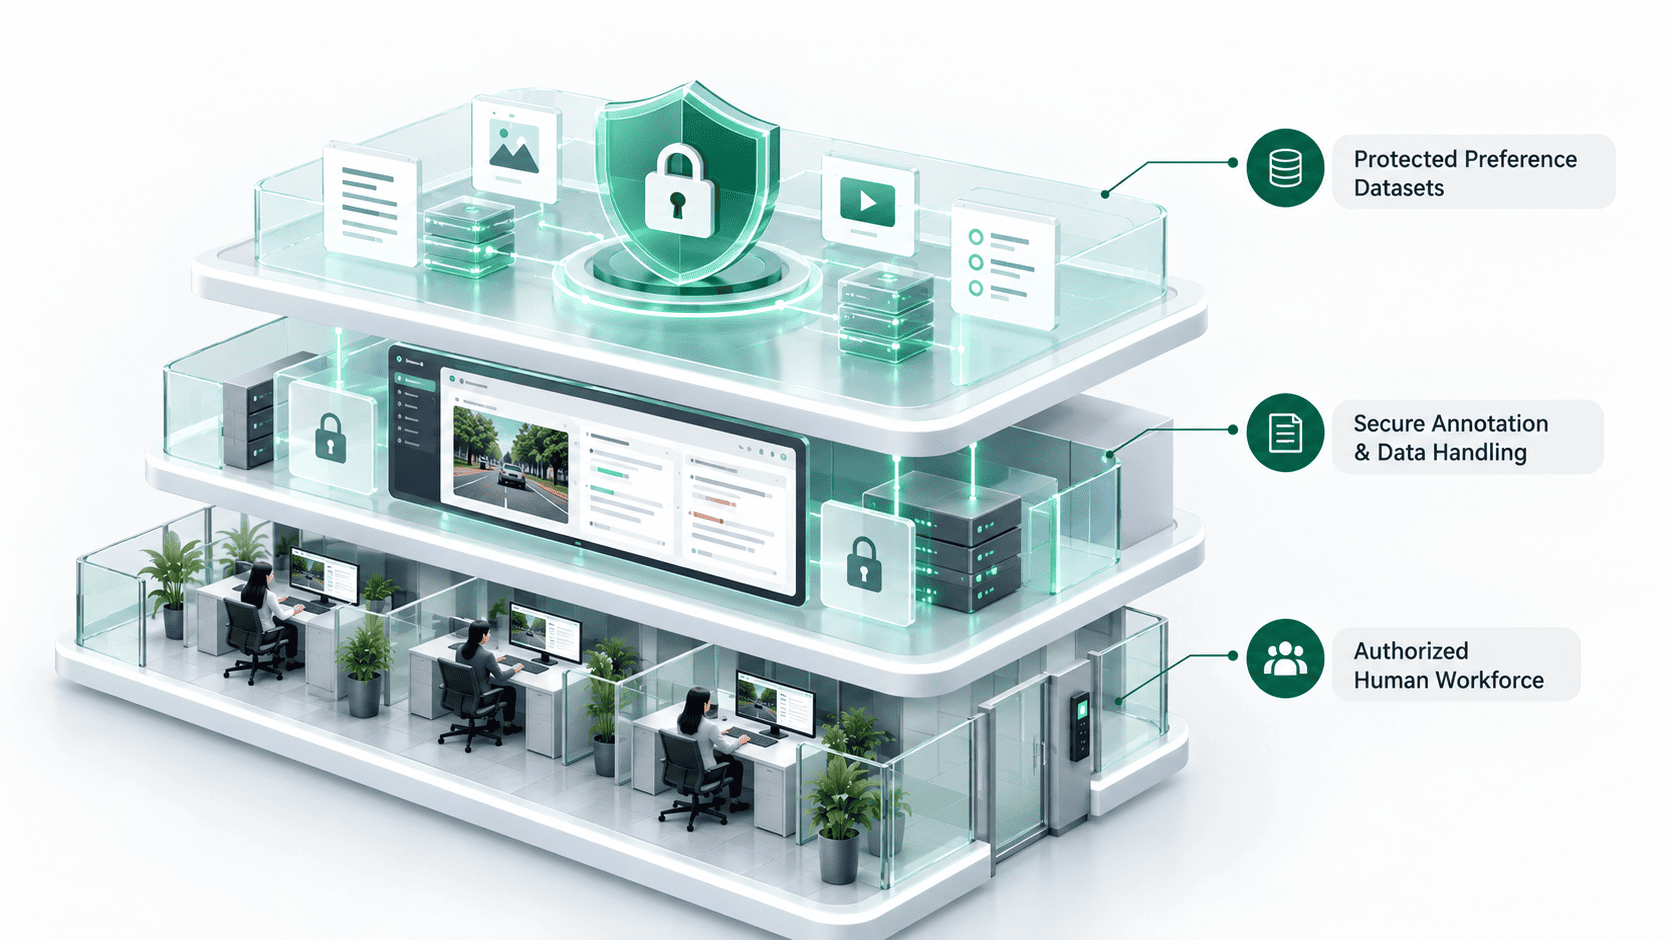
Frontier AI annotation helps enterprises manage proprietary prompts, model outputs, evaluation data and preference datasets through controlled workflows. Our in-house workforce supports project oversight, data intake, access management, processing, delivery and retention or deletion, aligned with approved security controls and compliance requirements.
Frequently Asked Questions
SFT uses instruction-response examples for supervised model adaptation. RLHF incorporates human feedback into a broader training process. DPO uses preference comparisons to optimize model behavior. The data requirements depend on the training method and implementation.
Data-handling requirements should be agreed before work begins. Buyers should confirm access controls, approved processing environments, confidentiality arrangements, retention practices, and deletion requirements relevant to the engagement.
Depending on the task, a VLM may use image-text pairs, captions, visual question-answer examples, grounded descriptions, video-related labels, and preference data involving visual context.
The appropriate method depends on the task. Agreement may be evaluated using categorical agreement, ranking comparisons, or task-specific visual annotation measures. Any published metric should include its definition and measurement scope
Video-text alignment connects language descriptions to relevant video frames, timestamps, or temporal events, depending on the annotation specification.
A defined workforce structure can support accountability, training consistency, project coordination, and oversight. Buyers should verify how the provider's actual staffing model supports these requirements.
With appropriate visual grounding and evaluation labels, annotation can help identify responses that are unsupported by the available visual evidence. It does not guarantee that a model will never hallucinate.