Computer Vision Model Training
LabelOps delivers custom AI model development services for computer vision, NLP, and speech and audio applications, powered by high-quality annotated training data. From model fine-tuning and retraining to evaluation and testing, we help enterprises optimise model performance against specific business and operational requirements. Our end-to-end workflows support deployment and integration across cloud, on-premises, and edge environments to align AI solutions with enterprise infrastructure and business goals.
NLP Model Training
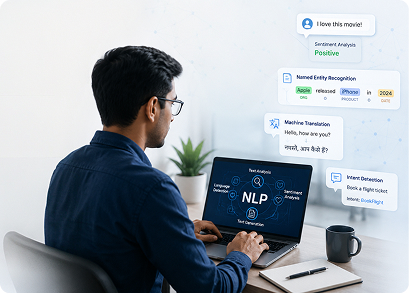
Develop natural language processing models for text classification, named entity recognition, and sentiment analysis, with workflows covering data preparation, annotation, model development, and performance evaluation.
Speech & Audio Model Training
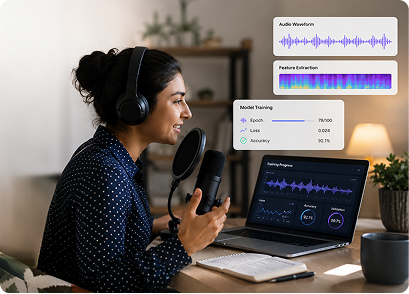
Prepare and train models for speech recognition, audio classification, and related audio-processing applications using appropriately labeled datasets, supporting transcription, voice-enabled systems, and call analytics.
Model Fine-Tuning & Retraining
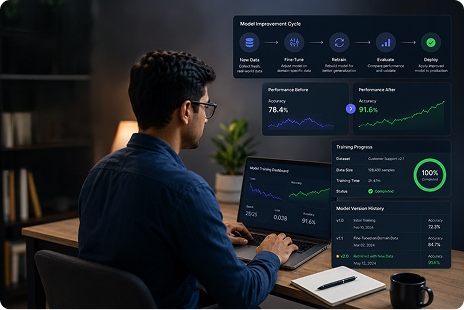
Adapt existing models to new requirements using relevant training data and iterative improvement workflows, including fine-tuning, retraining, targeted data collection, or active learning to close performance gaps.
Model Evaluation & Testing
Evaluate trained models against defined benchmarks and application-specific requirements, measuring accuracy, precision, recall, F1 score, robustness, and other relevant performance measures for reliable outcomes.
Deployment & Integration
Prepare trained models for integration into the intended application or infrastructure, with deployment options across cloud, on-premises, and edge environments based on your solution architecture and requirements.
Frequently Asked Questions
Custom AI model training services involve developing or adapting machine learning models for specific tasks using relevant training data. Depending on the project, the process may include data preparation, model training, evaluation, fine-tuning, and deployment.
LabelOps' listed services include computer vision, natural language processing, and speech and audio model training. The suitable model type depends on your use case, available data, and technical requirements.
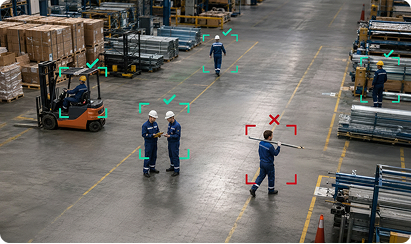
Computer vision model training uses labeled visual datasets to teach models to interpret images or video. Common tasks include object detection, image classification, and image segmentation for applications such as industrial inspection, retail analytics, and autonomous systems.
Natural language processing (NLP) model training develops models that process and analyze text. Common tasks include text classification, named entity recognition, and sentiment analysis.
Speech and audio model training uses audio datasets to develop models for tasks such as speech recognition and audio classification. Depending on the application, these models can support transcription tools, voice-enabled applications, and call analytics.
Fine-tuning adapts an existing pretrained or trained model using additional task-specific data. Retraining involves training a model again using an updated or revised training dataset and workflow. The appropriate approach depends on the model, the available data, and the performance issues being addressed.